The idea, in plain English
Start here.
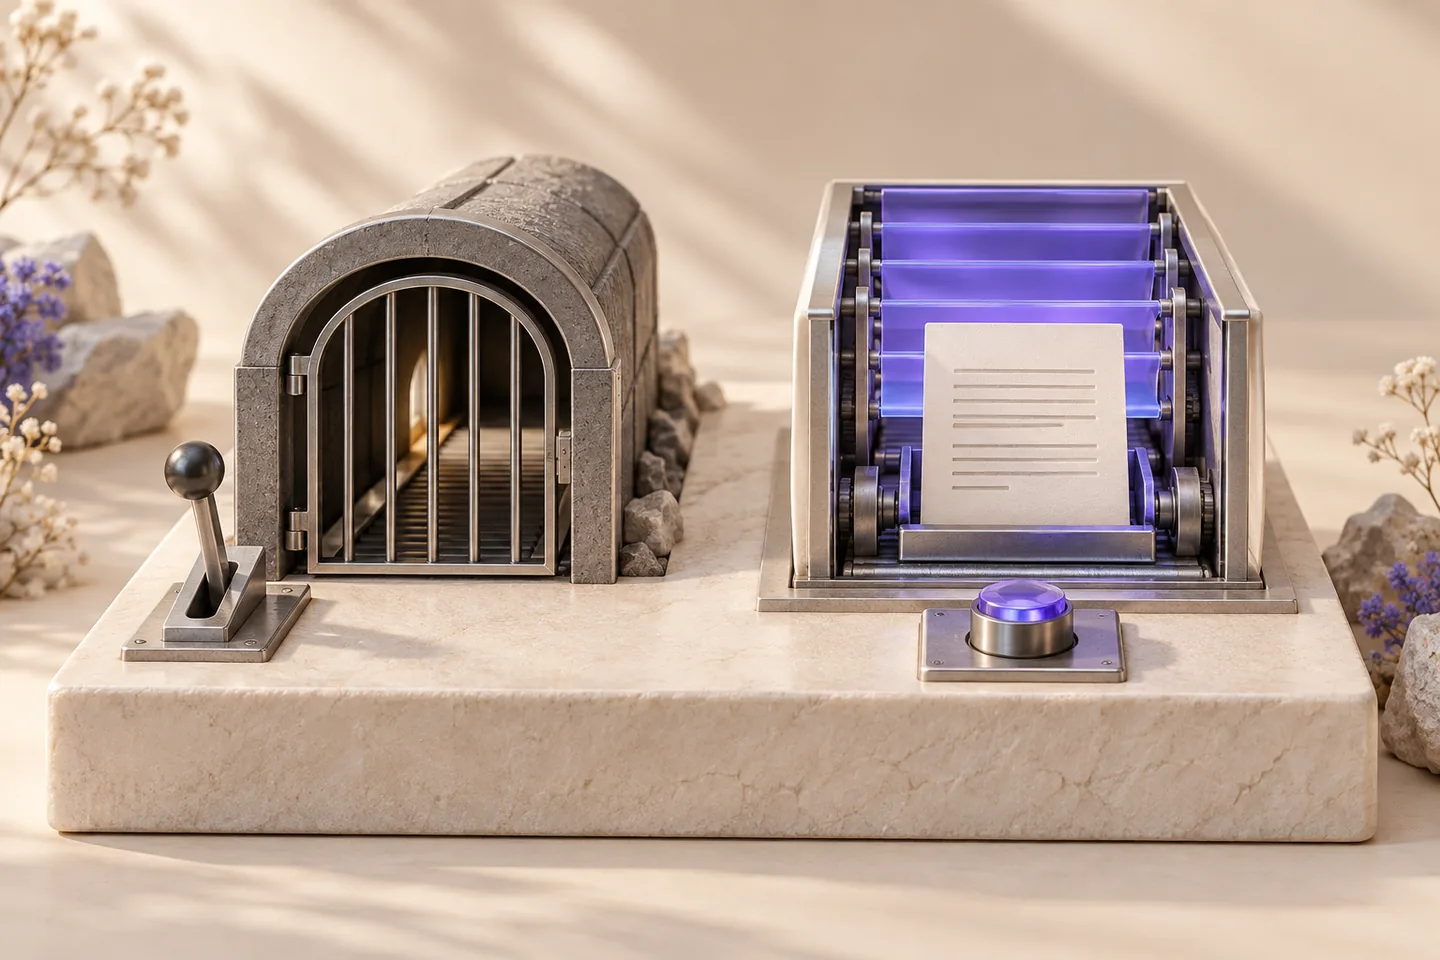
Robots.txt manages crawler access to URLs. A noindex rule asks a supporting search engine to exclude a page from its index, but the crawler must be able to fetch the page and read that rule. Neither control protects private information from people.
A page can open perfectly in your browser and still carry a setting that keeps it out of search. Another page can be blocked from crawling yet have its address appear in a result. The useful first question is what you want to control: fetching a URL, listing a page or access to confidential material.
A few words you’ll meet.
OPEN WHAT YOU NEED ↙Crawling
Fetching a URL and its available resources to examine what the server delivers.
Indexing
Processing information for a search index. Being accessible does not guarantee that a page will be indexed or shown for a query.
Robots.txt
A public file at the site root with instructions for supporting crawlers about which URLs they may request.
Noindex
An indexing rule in a page’s robots meta tag or an HTTP response header. Google must fetch the resource to discover the rule.
Write the intended outcome first
Choose one real URL and describe the desired behavior. A public workshop guide should be available to readers and eligible for search. A public confirmation page may need to stay accessible without appearing in search. A confidential staff document needs actual access control. These are different requirements, even if someone describes all three as a visibility setting.
Record the environment too. A setting intended for a protected preview can be harmful when copied to a public site. Before editing anything, save the current rules and identify who owns the change. A visible page is not evidence that a crawler received the same response.
Keep the two crawler controls separate
Robots.txt Disallow tells a supporting crawler not to fetch matching URLs. Google can still discover an address from links and may list the URL without reading the blocked page. Disallow is therefore unsuitable as a dependable way to remove a public HTML page from search.
A noindex rule in the HTML head, such as <meta name="robots" content="noindex">, addresses indexing. An X-Robots-Tag: noindex response header can also communicate the rule, including for non-HTML files. Google must be allowed to fetch the resource to see either version. Putting a noindex line in robots.txt is not supported by Google.
- Crawl control: may this supporting crawler request the URL?
- Indexing control: may the fetched page be included in search?
- Access control: which people or clients may obtain the information?
Two questions before a search result

Look for conflicting instructions
Suppose a public page has both a robots.txt block and a noindex tag. Adding the tag does not help Google if the block prevents it from fetching the page. Review the intended outcome and arrange for the crawler to read the indexing rule. Do not unblock genuinely confidential information as a troubleshooting shortcut; secure it with appropriate authentication instead.
Check the delivered response rather than relying only on a CMS checkbox. A template can add a meta rule and a server can add a response header. Inspect both where relevant, and review whether robots.txt blocks resources needed to understand the page. For a public page that should be eligible for search, an accidental noindex is a different problem from a blocked crawl.
Verify the change without promising timing
After an authorized change, confirm the actual robots.txt, page response and applicable meta or header rule. Use Search Console’s URL Inspection information to examine what Google fetched and distinguish the indexed record from a current live test. Write down the URL, observation time and result, including what has not been checked.
A saved rule and a changed search result are separate observations. Google needs another crawl to process a newly added noindex, and there is no fixed removal deadline for every page. Requesting a recrawl is not proof that the change has already been processed. If urgent removal is necessary, consult Google’s current removal documentation and still resolve the underlying access or indexing requirement.
Three pages, three requirements
Fictional teaching cases. This is a control-selection exercise, not a live site audit or a promise of index changes.
| Page | Requirement | Appropriate direction |
|---|---|---|
| Public workshop guide | Readers and search should be able to access it. | Check crawl access and unintended noindex; eligibility still does not guarantee indexing. |
| Public booking confirmation | Customers can open it; it should not appear in Google Search. | Use a readable noindex rule and verify the delivered response. |
| Confidential staff file | Only authorized staff may obtain it. | Use appropriate authentication and permissions; robots settings are not security. |
Put it into practice
Diagnose a blocked instruction
A fictional public confirmation page remains visible as a URL in Google. Its HTML contains noindex, but robots.txt disallows the same address. No confidential customer information is present.
- Write the desired reader access and search behavior.
- Explain which instruction Google cannot read and why.
- Propose a controlled change that makes the intended indexing rule readable.
- List the delivered-response and Search Console checks you would record.
- State what you cannot promise about the processing date.
Keep your working notes in your own document. This page saves only your completion check, not your answers or customer data.
Check your understanding
Make the call.
Choose an answer for each question. Then compare the reasoning.
You have a useful next step.
- Start with the required access and search behavior for a specific URL.
- Robots.txt controls fetching; noindex must be read to affect indexing.
- Verify actual responses and separate implementation from later search processing.
Completion is your own learning record. Quiz scores and practice checks are saved separately, on this browser.
Sources & context
The sources below explain the factual foundations and editorial methods used in this lesson. Worked examples, planning models and exercises are illustrative teaching material.
- Google: Introduction to robots.txt
Primary guidance on crawl access, discovered blocked URLs and the limits of robots.txt as privacy or indexing control.
- Google: Block indexing with noindex
Primary guidance on meta/header implementations, required crawl access and verification. No processing deadline is promised.